AGIBOT Unveils GO-3 Preview, Takes Top Spot on Three Embodied AI Benchmarks

The new embodied foundation model connects pre-training, post-training and post-deployment learning, helping robots develop general-purpose capabilities and continuously improve through real-world experience.


【SHANGHAI, China, October 29, 2026】AGIBOT today unveiled GO-3 Preview, an embodied foundation model that supports large-scale learning across the full lifecycle of pre-training, post-training and post-deployment. The model has also secured first-place rankings on three major embodied AI benchmarks—RoboDojo, RoboTwin and RoboColiseum—and will be fully open-sourced by the end of 2026.


1793270088628853.jpg

GO-3 Preview ranks first on three major embodied AI benchmarks: RoboDojo, RoboTwin and RoboColiseum.


Built on AGIBOT's proprietary embodied-native architecture, WRAM (World Reasoning Action Model), GO-3 Preview unifies task understanding, future-state prediction and action generation to enable robots to generalize across tasks and perform precise manipulation. Together with Genie Evolver, AGIBOT's hybrid post-training system, and Genie Master, its embodied agent framework, GO-3 Preview forms an integrated learning system spanning pre-training, post-training and real-world deployment. AGIBOT calls this approach "full-lifecycle scaling," designed to help robots develop general capabilities, refine their skills through interaction and continuously improve by learning from real-world work.


Large language models have made remarkable advances in reasoning and knowledge-based tasks, but working in the physical world requires more than understanding instructions. Tasks such as grasping small objects and assembling components demand the ability to anticipate environmental changes, manage contact forces and execute precise physical movements. For embodied AI, the challenge is not simply to scale model training, but to extend learning across the entire lifecycle. Rather than developing capabilities solely during pre-training, robots must also learn through post-training interactions and continue adapting after deployment. GO-3 Preview is designed around this principle: enabling robots not only to learn how to perform tasks, but also to become more capable through performing them.


Pre-Training Scaling: Building General Capabilities That Transfer Across Tasks

Consider a simple instruction: "Pick up the cup." The object could be a mug with a handle or a smooth glass, positioned in the middle of a table or surrounded by clutter. To handle such variations, a robot cannot simply memorize specific objects or fixed movements. It needs general-purpose capabilities that transfer across tasks and environments. During pre-training, GO-3 Preview addresses this challenge by scaling both data and model capabilities through its embodied-native WRAM architecture. This approach is designed to help robots learn transferable skills and adapt more quickly to unfamiliar situations.


WRAM connects task understanding, future-state prediction and action generation within a unified architecture. Three core designs — CoAE, SVP and KASO — work together to help the model understand what needs to be done, anticipate what may happen next and generate the actions required to complete a task.


CoAE (Control-Oriented Autoencoder) extracts visual representations tailored to robotic control, preserving information about object positions, shapes and spatial relationships. By linking visual perception to physical action, it provides a foundation for predicting future states and generating appropriate movements. 


SVP generates a complete prediction of future states in a single step based on current observations and task conditions. The action-generation module then learns how to move from the current state toward the predicted outcome. By connecting the robot's observations with possible future developments, SVP helps the model anticipate changes rather than relying solely on immediate visual input.


KASO addresses the challenge of multiple plausible outcomes in physical environments by selecting future predictions that are more consistent with the actions actually taken during training. These selected predictions are used for joint learning, helping align future-state prediction with action generation so the model can learn actions that lead to physically consistent outcomes.


Building on these three mechanisms, GO-3 Preview scales learning through both data and model development. On the data side, the model learns from heterogeneous sources. Human first-person videos provide rich examples of object interactions and task execution, while robot trajectories establish connections between observations, actions and their physical outcomes. On the model side, improvements in learning capacity help the system organize these diverse experiences and translate them into general capabilities that can be applied across different tasks. The goal is not simply to learn more examples, but to make better use of those experiences when encountering new situations.


1793268139703930.gif

GO-3 Preview learns from human first-person videos and robot trajectories, connecting object interactions and task execution with actions and physical outcomes.


Following pre-training, GO-3 Preview demonstrates task adaptation in both zero-shot and few-shot settings. In zero-shot scenarios, the model can apply previously learned capabilities to new tasks without requiring task-specific supervised fine-tuning on physical robots. This demonstrates its ability to transfer general skills to unfamiliar tasks and environments. For more complex operations, GO-3 Preview can further improve through few-shot learning, using a small number of demonstrations to adapt its capabilities.


Zero-shot.gif

Zero-Shot Task Demonstrations


LEGO assembly provides one example. The task requires a robot to identify individual components, grasp them precisely, align their positions and insert them correctly. With limited additional demonstrations and fine-tuning, the model can learn these precise manipulation skills, while an embodied agent coordinates the individual steps into a complete assembly process. Together, these examples demonstrate how pre-training can establish a general foundation that supports both direct task transfer and further adaptation.


Post-Training Scaling: Improving Through Physical and Virtual Interaction

General capabilities alone are not enough for robots to perform every complex task reliably. Just as people refine their skills through repeated practice, robots need opportunities to experiment, receive feedback and improve their action strategies. For GO-3 Preview's post-training stage, AGIBOT developed Genie Evolver, a distributed hybrid-environment training system that combines a fleet of 100 physical robots with physics simulation and world models. By expanding the scale and diversity of interactions, Genie Evolver enables robots to learn from both physical execution and virtual exploration, continually refining their action policies through feedback. The system brings together three complementary learning environments.


Physical Robots: Learning from Collective Experience. In real-world environments, Genie Evolver uses CEL (Collective Experience Learning) to aggregate execution experience across multiple robots. Successful trajectories provide examples of effective actions, while the context surrounding failed attempts helps identify where improvements are needed. By retrieving relevant successful experiences and updating shared strategies, CEL allows lessons learned by individual robots to benefit the wider fleet. Rather than requiring each robot to learn everything independently, the system makes collective experience reusable.


1793267608731423.gif

  Genie Evolver enables robots to learn and improve through shared experience.


Physics Simulation: Expanding the Range of Interactions. Physics simulation provides controlled environments in which robots can practice and be evaluated under different conditions. These environments expand the range of physical interactions and scenarios available for training, while allowing experiments to be repeated under consistent conditions. This makes it possible to explore alternative strategies and improve robustness across a broader range of situations.


1793267666236866.gif

Physics simulation helps robots practice and improve across diverse scenarios.


World Models: Exploring Multiple Possible Futures. World models allow the system to learn more from each real-world experience by exploring alternative outcomes. Rather than treating an interaction as a single sequence of actions, Genie Evolver can revisit critical decision points, test different possible actions in a world model, and predict and compare their outcomes. Feedback from these explorations is then used to refine action strategies, which can subsequently be tested on physical robots.


1793267776528763.gif

 World models help robots explore possible outcomes and refine their actions.


Together, these environments create a continuous improvement process in which real-world execution, simulation and future-state exploration reinforce one another. AGIBOT demonstrates this approach through several manipulation tasks requiring precision, adaptation and rapid decision-making.


In tabletop curling, the robot must control both the force and angle of each shot. Too little force may fail to move an opponent's stone, while excessive force can send the robot's own stone outside the scoring area. Success depends on striking the right balance while accounting for the positions of the stones. According to AGIBOT, after just a few hours of practice combining real-world interaction and world-model learning, the robot achieved a higher win rate than typical human players.


1793266665969268.gif

Tabletop Curling


Block extraction introduces a different challenge: each successful action changes the conditions for the next. When a red block is removed, the positions and orientations of the remaining blocks may shift. These changes can affect subsequent decisions, making it difficult to complete the task through a fixed sequence of movements. By drawing on accumulated experience, the robot can reassess the stack after each action, adjust its strategy and continue removing the target blocks until the task is complete.


1793266913337767.gif

Block Extraction


Throwing a ball into a moving basket presents a more dynamic challenge. Unlike a stationary target, a moving basket gives the robot less time to observe, predict and react. The robot must rapidly identify the basket's position while adjusting the force and angle of its throw in real time. Accurate predictions of fast-changing conditions are equally important, enabling the robot to coordinate its movements and release the ball at the right moment. Together, these demonstrations illustrate how GO-3 Preview can improve its manipulation capabilities through repeated interaction, feedback and strategy refinement.


Post-Deployment Scaling: Learning and Improving Through Real-World Work

Even with extensive pre-training and post-training, robots inevitably encounter situations they have never seen before once deployed in real-world environments. Traditionally, addressing such problems has often required human engineers to modify code, collect additional data or manually adjust the robot's behavior. This limits how quickly capabilities can improve after deployment. AGIBOT's approach is to extend learning into the deployment stage itself, allowing robots to improve while carrying out real tasks.


Through its embodied agent framework, Genie Master, AGIBOT connects planning, execution, feedback and experience retention to help robots adapt to new challenges and continuously develop their capabilities. Genie Master introduces EEP (Embodied Execution Protocol), which standardizes four categories of interfaces: capabilities, guidance, feedback and continuity. These interfaces allow an embodied agent to identify which robot capabilities are available, determine how tasks should be executed, assess whether the results meet the intended requirements and track work that remains unfinished. By connecting these functions, Genie Master helps robots coordinate task execution, identify failures, recover from exceptions and retain useful operational experience.


Crucially, this experience can contribute to future improvement through two complementary learning pathways. The first turns operational experience into long-term memory. During task planning and execution, the system records both successful and unsuccessful attempts, capturing lessons that can inform subsequent decisions. At the end of each day's operations, the model consolidates reusable knowledge from these experiences into long-term memory. When similar tasks or situations arise, the agent can retrieve relevant past experiences to guide task planning, improve decisions and support recovery from failures. This allows lessons learned during one task to become useful knowledge for future operations.


The second pathway turns execution experience into improved action policies. As the agent assists with execution, takes over when necessary and supports recovery from failures, the system generates trajectories and feedback that capture problems, adjustments and outcomes. These records can be processed and used for further training of the robot's action policies. Over time, effective adjustments can be incorporated into model parameters, turning practical experience into capabilities that can be reused in subsequent tasks. This creates a feedback loop in which deployment not only puts existing skills to work, but also generates new learning opportunities.


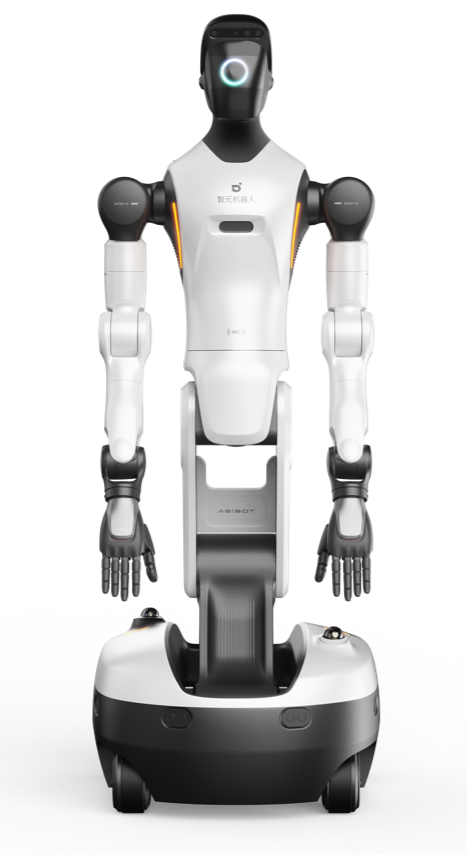
AGIBOT has demonstrated this approach using its Genie G2 robot in a real convenience store environment. Powered by Genie Master, the robot was able to identify the causes of task failures, adjust its strategies and accumulate experience while performing operational tasks. According to AGIBOT, the robot continued improving across multiple complex tasks requiring precise manipulation without relying on human demonstrations or manual tuning. The company describes the demonstration as an example of autonomous improvement without a human in the loop, in which the robot learns from its own operational experience rather than depending entirely on external intervention.


AGIBOT also describes this as a demonstration of Physical RSI (Recursive Self-Improvement in the Physical World) in a real business environment, extending the concept of self-improvement beyond simulation and laboratory settings. The significance of this approach lies in connecting real-world execution with continued learning. Instead of treating deployment as the final stage of model development, Genie Master makes operational experience a resource for ongoing improvement.


1793267309362212.gif

Robot Working in a Convenience Store 


From GO-1 to GO-3: Extending Scaling Across the Full Learning Lifecycle

From the ViLLA framework introduced with GO-1 to the action chain-of-thought approach pioneered in GO-2, AGIBOT has continued expanding the capabilities of its embodied AI models. GO-3 Preview represents the next step in this development, extending scaling beyond pre-training to encompass post-training and learning after deployment. Its first-place rankings on RoboDojo, RoboTwin and RoboColiseum, together with demonstrations of task transfer, complex manipulation and real-world adaptation, highlight the potential of this full-lifecycle approach.


Rather than relying on improvements at a single stage, GO-3 Preview, Genie Evolver and Genie Master connect three essential processes: developing general capabilities through pre-training, refining action strategies through physical and virtual interaction, and turning real-world operational experience into continued learning. As data, feedback and experience form a continuous cycle, the system is designed to help robots expand their capabilities over time. For AGIBOT, full-lifecycle scaling represents a path from acquiring skills to applying, reusing and improving them — enabling robots to turn what they have learned into practical performance and every real-world task into an opportunity to become more capable.


For more information, please visit AGIBOT.com and follow AGIBOT on:
X: https://x.com/AGIBOTofficial
LinkedIn: https://www.linkedin.com/company/agibot/
YouTube: https://www.youtube.com/@AGIBOTofficial
Instagram: https://www.instagram.com/agibotofficial/
TikTok: https://www.tiktok.com/@agibotofficial
Facebook: https://www.facebook.com/AGIBOTofficial/


About AGIBOT
AGIBOT is a pioneer in the global general-purpose AI robotics industry, with its core technology focused on embodied AI. AGIBOT's "Three Intelligences in One" architecture integrates Locomotion Intelligence, Interaction Intelligence, and Manipulation Intelligence into a unified embodied system. Its portfolio spans humanoid robots, quadrupeds, dexterous systems, and commercial cleaning solutions. In September 2026, AGIBOT announced that its 20,000th robot had rolled off the production line.